In short
For a monetized character feed, rank open video models by license first and quality second. Wan 2.2 (Apache 2.0) is the safe default and has no sound. LTX-2.5 adds synchronized audio and a $10 million revenue line. MiniMax H3 is the most capable but excludes the US, EU, UK and South Korea. Kandinsky 6.0 Lite is MIT and brand new, with 5-second clips and sound.
A reel is nine by sixteen, five to fifteen seconds long, and it has to show the same face as last week's post. Four open video models can do that in ComfyUI right now, and they differ less in quality than in what they allow you to do with the result. Wan 2.2 has no revenue cap. MiniMax H3 is not licensed for the US, the EU, the UK or South Korea.
This list ranks them for one job: a recurring character posting vertical clips to a monetized account. We have not run a benchmark of our own. Specs, licenses and dates come from each model's primary page, and the experience reports come from public Hugging Face threads. Where nobody has published a number, the article says so.
How we ranked them
- License first. A model you cannot post from is worth nothing, so a clean grant outranks a nicer demo. Read the license of the exact checkpoint you download.
- Vertical output. Does the model document a portrait size or a 9:16 option, or do you crop a landscape clip?
- Sound. Reels with speech or ambience need audio, and a separate audio pass is extra work for every clip.
- Hardware and failure reports. What people say about 12 and 16 GB cards, and what breaks when they try.
- Identity. Can the face of your character survive from the still to the clip? Our guide to a consistent character set covers how to make the input worth keeping.
The ranking
- 1
Wan 2.2
The safe default for a monetized feed. Apache 2.0 means no revenue cap and no territory map, and ComfyUI has a documented workflow for it. You add the sound yourself.
Best for: Silent hooks, loops and B-roll for a character who also talks in separate audio
- Apache 2.0 on the model cards
- TI2V-5B documents 704 by 1280 portrait at 24 fps
- Comfy docs say the 5B model should fit 8 GB with native offloading
- The largest ecosystem of workflows and repackaged files
- No audio in the generation; our [Wan 2.2 reels guide](/guides/ai-influencer-video-wan-2-2) describes the separate lip-sync chain
- The card's own commands ask for 24 GB (5B) or 80 GB (A14B) before offloading
- Released July 2025, so it is the oldest model here
- 2
LTX-2.5
The easiest way into video with sound. Official ComfyUI templates, quantized checkpoints, and users running it on a 12 GB card. The face is where it loses, and the license has a ceiling.
Best for: Image-to-video reels with sound on a mid-range GPU, for accounts under USD 10 million in revenue
- Synchronized audio and video from one 22B model
- Official ComfyUI templates, int8 checkpoints and an upscaler
- A reported 12 GB RTX 3060 run: 15 seconds in about 5 minutes at 960 by 544
- Portrait works: a user guide ran a 5 second 736 by 1280 clip on a 12 GB RTX 4070, peaking at 11.4 GB
- Several threads report identity drift from the still, including one called a disaster for i2v
- VAE decode can hang on 10 second clips until tiles are shrunk
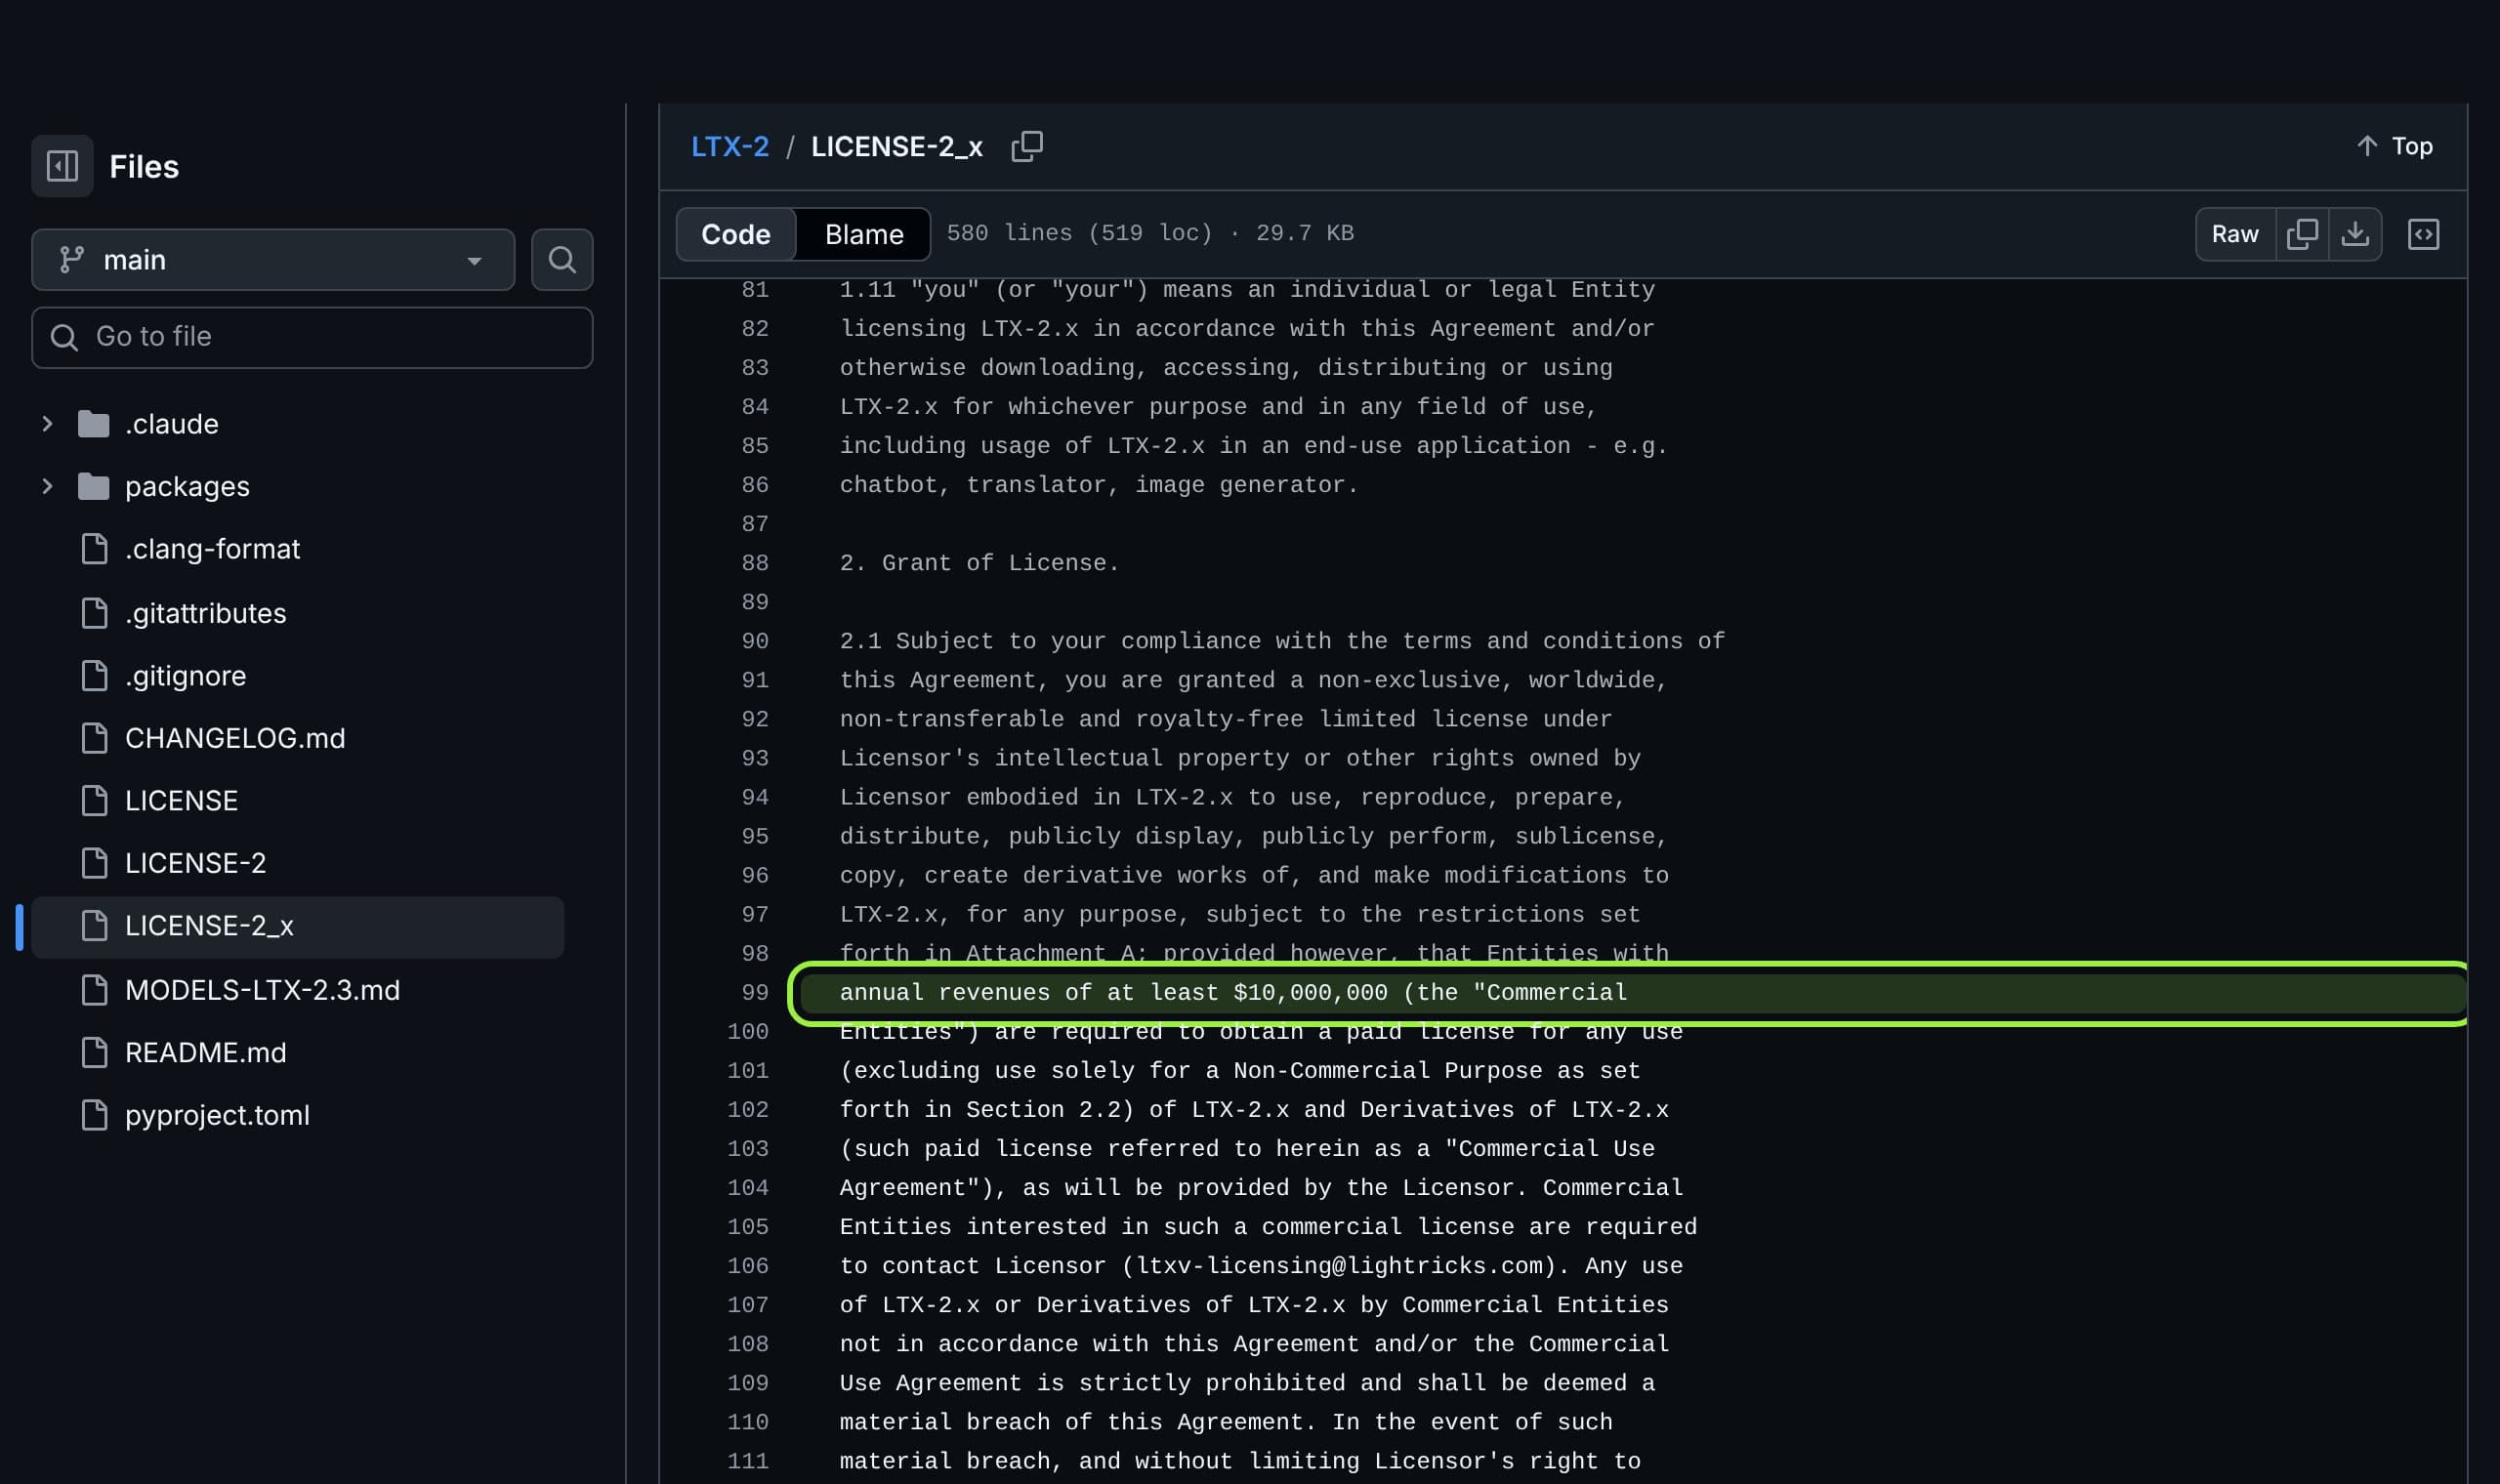
- Free commercial use stops at USD 10 million in annual revenue, counted across affiliates
- The weights are gated behind a license click
- 3
MiniMax H3
The most capable open model for a talking character, and unusable for many of the people who want it. Outside the excluded territories it can sit at number one. Inside them it does not exist for you.
Best for: Talking reels from up to nine reference photos, if you are outside the US, EU, UK and South Korea
- 9:16 is a listed aspect ratio; 4 to 15 second clips at 24 fps
- Native stereo audio at 32 kHz
- Ref2VA takes up to 9 images, 3 videos and 3 audio clips as references
- Core ComfyUI support since 0.30.0
- The community license excludes the US, the EU, the UK and South Korea; see our [MiniMax H3 review](/blog/minimax-h3-comfyui-review)
- About 33B parameters and mixed reports on 12 and 16 GB cards
- Decode memory failures on long clips are open issues
- 4
Kandinsky 6.0 Lite
The one to watch, not yet the one to build on. MIT license, a 3B model with synchronized 44 kHz audio, and almost no independent testing a week after release.
Best for: Five-second hooks with sound where the license must be unquestionable
- MIT license on the model card
- 3B Lite and 29B Pro, each with a 10-step distilled checkpoint
- Lip-synced audio in the same pass
- A Full HD upscaler is included
- Clips are 5 seconds
- The only example size is 480 by 864 and no aspect ratio is claimed
- No VRAM figures, and the ComfyUI extension needs 0.38.0 or newer
- We found no independent quality tests
Side by side
| Spec | Wan 2.2 | LTX-2.5 | MiniMax H3 | Kandinsky 6.0 |
|---|---|---|---|---|
| License | Apache 2.0 | LTX-2.x Community License, free under USD 10M revenue | Community License, excludes US, EU, UK, South Korea | MIT (model card) |
| Size | 5B dense, or A14B MoE (27B total, 14B active) | 22B | About 33B | 3B Lite, 29B Pro |
| Sound | Not in the model | Synchronized audio | Stereo, 32 kHz | 44 kHz with lip sync |
| Clip length | 5 s (TI2V-5B) | Hosted Fast: 2 to 20 s | 4 to 15 s at 24 fps | 5 s at 24 fps |
| Vertical | 704 by 1280 | Portrait confirmed for hosted Fast and by a user | 9:16 listed | 480 by 864 example |
| Released | July 28, 2025 | August 11 to 12, 2026 | August 2026 | October 6, 2026 |
What people are downloading
Read this chart with care. Each bar is a different repository: Wan's is the repackaged ComfyUI bundle, MiniMax's is a third-party distilled release, and Kandinsky's is a Diffusers repo that ComfyUI users do not touch because the ComfyUI extension installs from the registry. Downloads show where the habit is, and the habit is Wan. They do not show which clip looks best.
What creators are saying
What creators are saying
A tester reports LTX-2.5 working out of the box on a 12 GB RTX 3060: a 15 second text-to-video clip at 960 by 544 in about five minutes, with no special tweaks.
Ten second image-to-video clips stalled at decode. Shrinking the tiled VAE tile from 768 to 512, or setting temporal size 64 with overlap 16, fixed it on an RTX 3090 and a 5070 Ti.
Same still, two models: LTX-2.3 kept the woman's face and LTX-2.5 gave a different person. Adding the 2.3 identity LoRA changed her face again.
ComplaintHugging Face, LTX-2.5 discussion
On MiniMax H3, only direct pass-through of the reference audio worked; otherwise output started with gibberish or replayed the reference file itself.
ComplaintHugging Face, MiniMax-H3 discussion
The pattern is consistent with the specs. LTX-2.5 is fast and cheap to run, and its trouble is the face. MiniMax is built around references and its trouble is audio plumbing. Neither thread says anything about Wan, which is quieter because it is older and better understood, not because it is flawless.
Pick in four questions
- 1
Where do you and your audience-facing business live?
If the answer is the US, EU, UK or South Korea, MiniMax H3 is out unless MiniMax grants you a license. Read definition 5 of its license before you download anything.
- 2
Will the account earn over USD 10 million a year?
If it could, LTX-2.5 needs a paid Commercial Use Agreement. Affiliates and companies under common control are counted together.
- 3
Does the reel need sound in the clip?
Yes: LTX-2.5 or Kandinsky 6.0 Lite, plus MiniMax H3 where it is licensed. No: Wan 2.2, and record the voice separately.
- 4
How much VRAM do you have?
Start with the smallest build: Wan TI2V-5B, the LTX int8 checkpoints, or Kandinsky Lite. Keep clips short and decode tiles small, then scale up once a clip finishes.
Verdict
Build on Wan 2.2 and test the others against it. Its license asks nothing of you, it has portrait sizes, and the most workflows and answers exist for it. Its gap is sound, which is a workflow problem you can solve once.
Add LTX-2.5 when the clip has to talk and you are under the USD 10 million line. Test the face on your own reference photo before you commit, because the public threads are full of identity complaints. Our LTX-2.5 image to video recipe shows how. Add MiniMax H3 only if you are outside the excluded territories. There it is the strongest talking-character option. Watch Kandinsky 6.0 until someone publishes side-by-side clips; an MIT license and 3B size make it the model most likely to change this ranking.
Switching video models should not mean rebuilding the character. Musetta runs on your own ComfyUI, installs the nodes a workflow is missing and keeps her reference photos in one place, so changing the model under her is a setting. See how it works, or the ComfyUI comparison if you are weighing it against building graphs yourself.
Questions
- Which open video model is best for Instagram and TikTok reels?
- There is no single winner. Wan 2.2 is the safest license (Apache 2.0) and has portrait sizes, but no built-in sound. LTX-2.5 and Kandinsky 6.0 add audio in one pass. MiniMax H3 is the most capable but its community license excludes the US, EU, UK and South Korea. Pick by license and by whether you need sound.
- Can I use these models for a monetized AI influencer?
- Wan 2.2 (Apache 2.0) and Kandinsky 6.0 (MIT, per its Hugging Face card) have no revenue cap. LTX-2.5 is free below USD 10 million in annual revenue, counted across affiliates. MiniMax H3 depends on where you are. Read the license of the exact checkpoint you download, because fine-tunes can carry their own terms.
- Do these models support 9:16 vertical video?
- MiniMax H3 lists 9:16 among its aspect ratios. Wan 2.2 TI2V-5B documents a 704 by 1280 portrait size. ComfyUI says the hosted LTX-2.5 Fast variant handles landscape or portrait, and a user guide ran 736 by 1280 locally. Kandinsky 6.0 shows a 480 by 864 example but makes no aspect ratio claim.
- How much VRAM do I need?
- Nobody publishes one matrix. Comfy's docs say the Wan 2.2 5B model should fit 8 GB with native offloading, while the Wan card's own command wants 24 GB. One user reports LTX-2.5 on a 12 GB RTX 3060. MiniMax H3 reports are mixed on 16 GB. Start small and keep clips short.
- Is the sound in these models good enough to post?
- Sound is the newest part. LTX-2.5 testers say lip sync holds up better than fine detail, and Kandinsky 6.0 was released only a week ago with no independent audio tests we could find. Listen to every clip with headphones before you post it, and add a disclosure that it is AI generated where the platform asks.
Sources
- 01LTX-2.5 model card · Lightricks, Hugging Face
- 02LTX-2.5 Day-0 Support in ComfyUI · Comfy Org, 2026-08-12
- 03LTX-2.x Community License Agreement (license text, Aug 11, 2026) · Lightricks, GitHub, 2026-08-11
- 04Wan2.2-TI2V-5B model card · Wan-AI, Hugging Face
- 05Wan2.2-I2V-A14B model card · Wan-AI, Hugging Face, 2025-07-28
- 06Wan2.2 in ComfyUI · ComfyUI docs
- 07Kandinsky 6.0 Lite model card · Kandinsky Lab, Hugging Face
- 08Kandinsky 6.0: video and audio generation in ComfyUI · ComfyUI Wiki, 2026-10-06
- 09MiniMax-H3 model card · MiniMax, Hugging Face
- 10MiniMax H3 Community License Agreement · MiniMax, Hugging Face, 2026-08-02
- 11LTX-2.5 I2V stuck on 10 second clips (discussion 15) · Hugging Face discussions, 2026-08-12
- 12LTX-2.5 on RTX 3060 (discussion 25) · Hugging Face discussions, 2026-08-12
- 13Character consistency in i2v (discussion 30) · Hugging Face discussions, 2026-08-13
- 14LTX-2.5 on 12 GB VRAM, i2v, vertical 736x1280 · note.com, 2026-08-12
- 15Hugging Face trending image-to-video models · Hugging Face, 2026-10-13
Researched and written by the Musetta editorial desk with AI assistance, from the sources above. Numbers come from those sources; nothing is benchmarked by us unless the article says so. Spotted an error? Tell us on Discord and we fix it.